Research
Multimodal Foundation Models (VLA)
Motivation
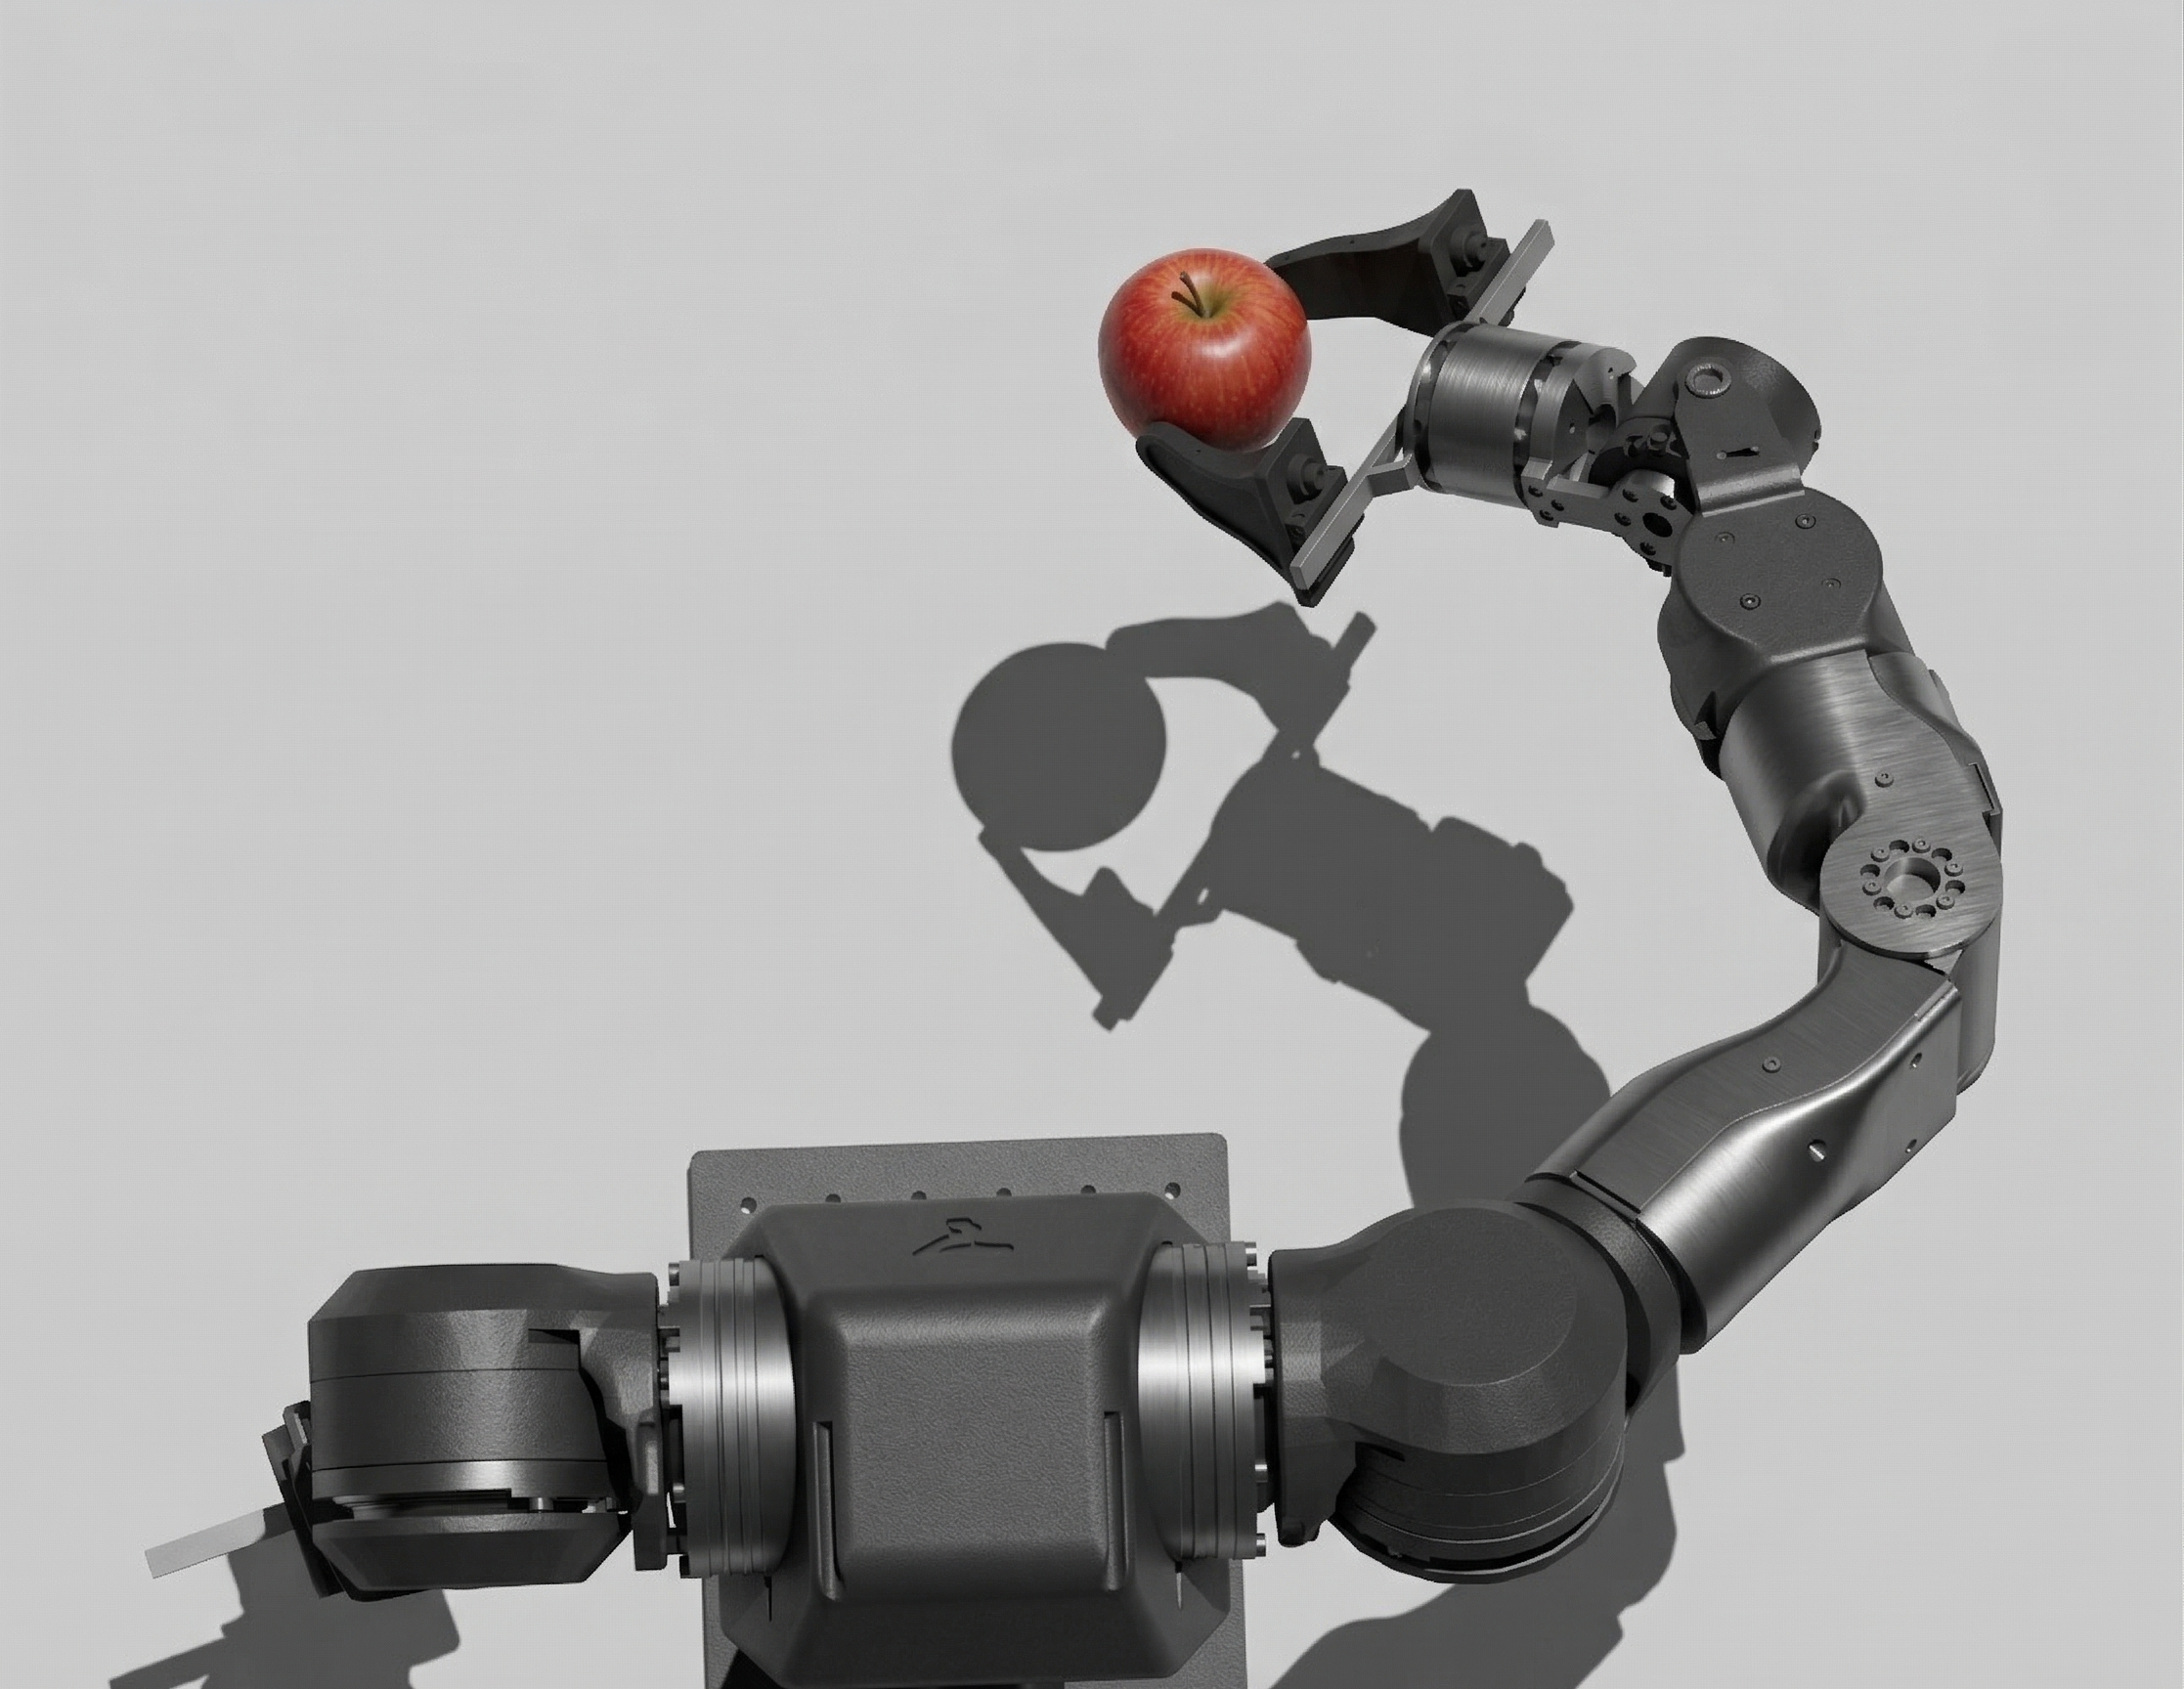
In an increasingly complex and dynamic world, robots need the ability to interpret multimodal information such as visual, linguistic, and proprioceptive data in order to perform versatile tasks effectively. Conventional systems often struggle to connect these different modalities, which limits the adaptability of robots in real-world scenarios. Developing unified multimodal architectures is therefore a crucial step towards truly autonomous robotic systems that can act intelligently in unpredictable, context-rich environments.
Research Direction
Our research aims to develop scalable Vision-Language-Action architectures that translate multimodal sensory inputs directly into executable commands. By exploring different architectural paradigms and focusing on scalability, we enable robots to reliably perform complex tasks in unstructured environments. Our goal is to create foundation models that seamlessly integrate sensor data and decision-making processes, thereby significantly expanding the scope of robotics applications.